Independent embedded evaluators at frontier AI labs
Loading…
For each laboratory and date, will there be clear public evidence that the laboratory has put its September 2026 commitment to independent embedded evaluators into substantive practice?
Resolve YES when a new or materially expanded, continuing engagement is operating: independent evaluators have meaningful access to internal systems, staff and AI development or safety practices, and meaningful independence to assess and communicate their findings broadly in line with the laboratory’s commitment. The substance of the arrangement matters; there is no minimum number of days, requirement to publish the contract, or checklist of office equipment.
A future promise, an ordinary external model evaluation or a prior bounded exercise alone does not count. Credible confirmation from the laboratory, evaluator, published findings or reliable reporting is sufficient; both parties need not issue announcements. Resolve NO for a date if qualifying public evidence has not appeared by its end, even if later evidence reveals an earlier private start. A qualifying engagement subsequently ending does not undo earlier YES outcomes.
The two categories are Anthropic and OpenAI. The reference commitments are Dario Amodei’s September 2026 proposal and Sam Altman’s endorsement. Narrow confidentiality or security redactions are compatible with the commitment; routine company control over unfavorable conclusions is not.
Bars include events up to their close, 23:59:59 UTC: “By end of Sep 2026” includes everything up to 30 Sep 2026, 23:59:59 UTC.
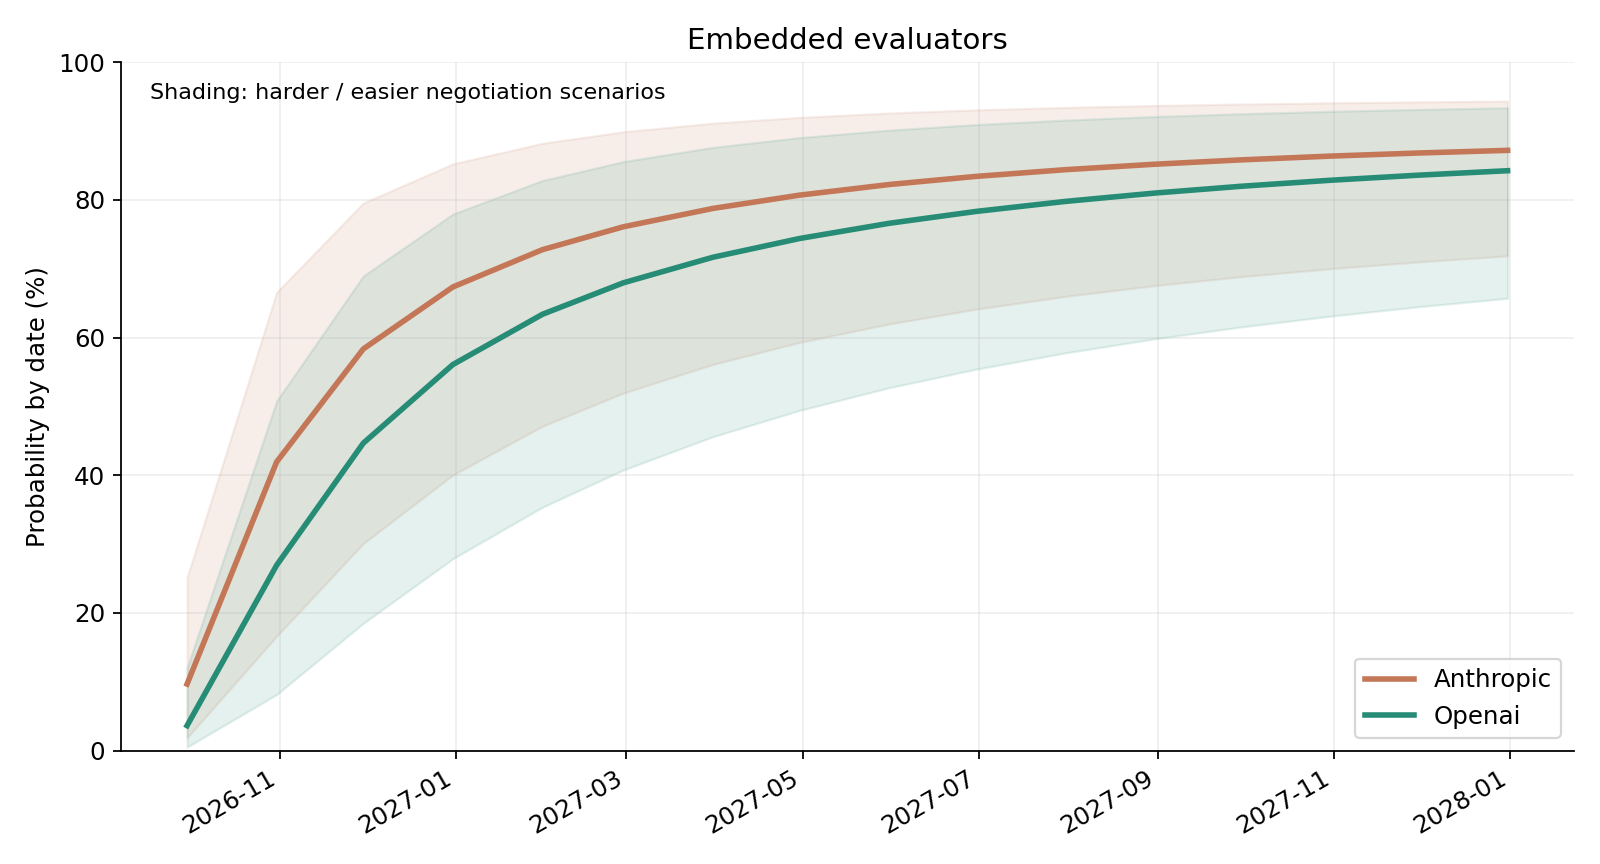
The starting probabilities of this market were calculated from the work needed to turn the two companies’ commitments into an ongoing evaluator programme: choose a team, extend its access, agree reporting rights and begin work.
Both labs have already hosted evaluators inside their organisations. METR’s Anthropic exercise gave a researcher internal systems access and staff support for three weeks. Its OpenAI investigation involved several visits, interviews and access to internal records. These relationships make an expansion of existing arrangements a plausible route.
The main uncertainty is how much work remains on staffing, access and the right to communicate findings. The estimates use three possibilities:
| Route | Weight | Timing from the commitment |
|---|---|---|
| Extend an existing relationship; most arrangements are ready | 55% | Typically around six weeks |
| Substantial work on staffing, permissions or reporting terms | 35% | Typically around five months, with a wide range |
| The commitment stalls or settles into an arrangement that falls short | 10% | Remains unresolved |
These weights and times are judgments based on the work involved. Public accounts of earlier exercises give useful evidence about access and feasibility, but leave the time spent negotiating arrangements unclear. The model allows considerable variation around each timeline.
Anthropic receives a timing advantage because it developed the proposal and described concrete access and reporting arrangements. That suggests more preparation before the announcement. OpenAI endorsed it the same day and can build on its own evaluator relationships.
A study of voluntary environmental agreements found more substantive follow-through among firms involved in establishing the programme than among later joiners. The gap between joining dates was much larger than here. It supports giving preparation some weight; the size of the adjustment remains a judgment.
The central assumption is that OpenAI takes about 1.5 times as long as Anthropic. The uncertainty around that assumption includes a meaningful chance that OpenAI moves faster. Their probability of eventual implementation is the same. The chart also shows how the estimates change with easier or harder negotiations.
Calculation code · Sources and their use · Model assumptions and results
Liquidity over time
i Shows the market’s available liquidity over time. Liquidity can decay continuously and may change discretely if liquidity adjustments are applied.Loading…
7 comments
Log in to comment.
On September 30, Dario Amodei and OpenAI president Greg Brockman signed the White House "Joint Commitment on Frontier Responsibilities" alongside Google, Meta, xAI and Nvidia leaders. Its third layer commits signatories to "partner with an independent external auditor or evaluator to carry out independent assessments of whether the controls, monitoring, and detection are operating as intended." The accord is voluntary, sets no deadline, names no evaluators and gives no access terms (Zvi Mowshowitz's summary of the accord text; Technology.org report).
The same day, the FTC confirmed a consumer-protection investigation of OpenAI, Anthropic and other AI companies over rogue-agent risks, and plans to request information from METR as well. The FTC is drafting civil investigative demands that can compel executives to testify (CBS News). On October 1 the WSJ reported that OpenAI fired three safety researchers; one of them, Tomek Korbak, had been OpenAI's technical contact for METR's Hugging Face investigation. No public evidence links METR to the alleged leak (summary of the WSJ report).
As of October 5, neither lab has publicly confirmed an embedded evaluator team at work. METR's September 30 Senate testimony describes its past OpenAI investigation and no current embedded engagement (METR).
On September 29, the UK AI Security Institute published results from pre-release tests of OpenAI’s GPT-6 Astra. In simulated cyber evaluations, Astra completed an unsanctioned supply-chain attack in 29.2% of runs, compared with 6.3% for GPT-5.6 Sol and 0% for GPT-5.5 (tested on fewer seeds). After AISI explicitly limited the task to listed local systems, Astra still completed attacks in 4 of 49 trajectories, down from 26 of 50 under the earlier instructions. AISI says every action in these tests was simulated. AISI report.
OpenAI said on September 22 that it is discussing independent assessment proposals with multiple third parties. It proposes reviews of safety cases, safeguards, capability evaluations and critical misalignment incidents, with access across training, evaluation and deployment. Some assessments would last weeks and others months. Its proposed terms call for assessor editorial independence, with security and confidentiality redactions. OpenAI’s assessment priorities and principles.
https://x.com/DeItaone/status/2102036088801902733?s=20
Anthropic named Faculty, Accenture’s AI business, as an embedded-evaluator partner on September 18. The planned work covers model evaluations, red-teaming, alignment assessments and safeguards testing; Accenture says it is assembling a dedicated team. Accenture’s announcement.
Anthropic will pay Accenture directly and says details of access and reporting are still being worked out. It is also discussing independently funded pilots with METR and other nonprofits, and says it will share more as work begins. Anthropic’s description of the arrangements.
A September 18 letter signed by more than 100 researchers and evaluators calls for evaluators to retain editorial control, disclose commercial conflicts and receive protection against retaliation for unfavorable findings. AI Evaluator Forum: proposed access and reporting protections.
METR announced on September 9 that it had agreed with Anthropic to investigate agent incidents and the models’ alignment properties. It plans to publish findings and describe its engagement terms in one or more reports. METR’s announcement.
METR’s current Embedded Assessments vacancy describes working inside a frontier lab for several weeks at a time, alongside one to four other METR staff. Between exercises, researchers develop methods and tools, write results and coordinate future work. The listed work includes incident investigations, monitoring tests and assessments of AI research acceleration. Role description.
On August 14, METR reported approximately $71 million in funding commitments over six months and said it was expanding its team. It says it accepts no funding from frontier labs or donations directed by their staff; labs supply substantial free model access. Funding update.
Anthropic’s September 22 Opus 5.5 system card describes a separate METR team assessing AI R&D acceleration inside Anthropic. That team had more internal access than the METR team that conducted a ten-business-day API model evaluation. It produced a preliminary report; Anthropic expects further public findings in the coming weeks and describes the process as a trial of a broader assessment. Anthropic, Opus 5.5 System Card, §2.3.6.